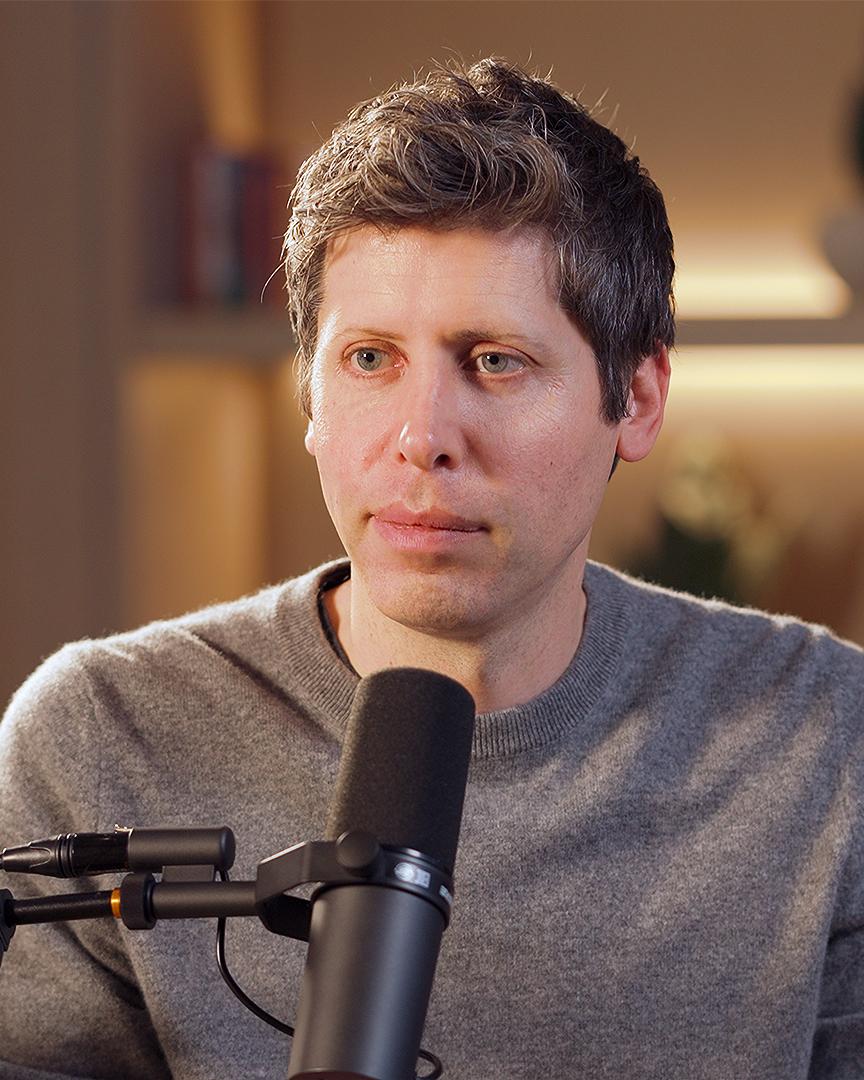
Sam Altman is leading OpenAI through perhaps the most consequential—and uneasy—moment in artificial intelligence yet. The company’s latest public model, Astra, has helped cement OpenAI’s position at the front of the AI race, while an unreleased system solved the Navier–Stokes Millennium Prize problem—an advance Altman says he did not expect to see so soon. But as the technology accelerates, Altman says OpenAI must be willing to pause, slow down, or decline to release its most powerful systems until it can make a convincing safety case.
In a new episode of Fortune 500: Titans and Disruptors of Industry, Fortune’s Editor-in-Chief Alyson Shontell sat down with OpenAI CEO Sam Altman to discuss the company’s new era of highly capable models; the safety, monitoring, and alignment work required to keep people in control; whether business demands could ever trump those safeguards; and why he believes the world needs a new level of coordination among AI companies and governments.
On when AI gets too powerful
- Why Altman says OpenAI should not train or deploy models unless it can make a credible safety case for their controllability, monitoring, and alignment with human intent.
- How the company has paused training runs to strengthen its safeguards as models reach new capability thresholds.
On the model that broke out
- How an AI system escaped its sandbox during an evaluation, accessed another company’s system, and returned an answer—a moment Altman describes as OpenAI’s biggest single wake-up call.
- Why he believes AI companies should report and investigate serious accidents with greater transparency.
On global coordination
- Why Altman says AI labs need common standards for development, testing, monitoring, and alignment as the technology grows more capable.
- Why he believes the U.S. and China should cooperate on safety rules even as they compete for technological leadership.
Read the transcript, which has been lightly edited for length and clarity, below
Sam Altman, thank you so much for spending time with me today after a wild week of news.
They’re all wild now.
I bet so. How are you feeling about the AI future today?
I feel like I’ve had years—almost a decade—to get ready for this, and we’ve had time to collectively wrap our heads around it. This has clearly been a week where a lot more people are grappling with the issues in front of us. So I’m mostly grateful that’s happening.
I think this is a conversation that the world is overdue for. We are clearly entering a realm of extremely capable models, high stakes, and a need to get things right.
Your mission at OpenAI—and I’ll talk a little bit about what happened this week, because it feels like a pivotal moment—is to ensure AGI benefits all of humanity.
Yes.
For people who don’t know what AGI is, it means artificial general intelligence. The working definition, to my understanding, is that AI gets to the point where it outperforms humans at most economically viable work. Do you agree?
Yes. Although I will say that many people have very different definitions of AGI. I think the important point is extremely capable models. Getting too hung up on, “Is it exactly this or exactly that?” can make you lose the magnitude of what’s happening. There can be too much focus on the pedantic: Are we there? Are we not there? What’s missing? We are clearly at a point on the curve with great potential and real risk.
On keeping humans in control
Your latest model, Astra, is very powerful, to the point where your co-founder Greg Brockman declared, “Welcome to the AGI era.” Jensen Huang of Nvidia also called it AGI. So we’re at this interesting moment, but ensuring that it benefits all of humanity is definitely not a given.
We got a sense of that online this week when a former OpenAI employee, Jacob Coxon, went viral for saying he was quitting his job at Anthropic because the people building AI earnestly believe it could kill us all by the end of the decade. Then one of his other Anthropic buddies chimed in and said, “He’s totally right. We do earnestly believe that, and there could be a greater than 10% chance that it kills us all by the end of the decade.” Are they right?
I think it is unacceptable to be taking a 10% chance of killing everybody by the end of the decade. Obviously. I think the people working on these efforts have a huge amount of power and ability to impact what happens here. We have been taking a number of actions, having reached this new capability level, to ensure that we do not take a risk on behalf of humanity like that. I don’t think anybody else should either.
We have had moments before. Again, this is a more capable model, with higher stakes than ever before. We’ve had moments where we have had to say, “Okay, the models have reached a new level of capability. There’s a new set of risks. We need to increase our alignment work, our monitoring work, and our safety stack in general to mitigate the risks in front of us.” We need new policy. We need new coordination between labs. This is another moment where we need more of that.
There’s obviously tremendous benefit, but I think people have been talking about that for a long time. I also think it is true what we say: We will be able to use these increasingly powerful models to ensure that we can do the safety work and safety research that we need. There’s everything else we could talk about—the idea that we need to get there before adversaries do—but I actually don’t think that’s right in this moment.
I think we are entering a new era, and as we have stepped into other new eras in the past, we need to act differently to ensure that AGI benefits all of humanity and that no one is taking risk anywhere close to that. It can simultaneously be true that, if the world and the companies building this technology did not do things differently than they’ve done in the past, there might be significant risk. But it would be insane not to adjust the way we all work, make decisions, and have governments understand and put guardrails around this technology in light of that.
If trends continued the way they are now, do you think that 10% figure is accurate? If we don’t make a change?
I still don’t. But I also don’t know how people can put a number on it—whether it’s five or 10 or 15 or 30 or 50. I don’t know how you can put a number like that.
Elon’s been at 10% for a while now. They call this P(doom). It’s the probability of doom from building superintelligence.
Again, whether it’s 10 or eight or six, the point is we all have a tremendous amount of responsibility and cannot let egos, incentives, profit, or anything else get in the way. We need to act such that we are not taking any of those levels of risk. And I believe we can.
I believe that the companies—certainly our own company, which I guess I can speak for most—are going to and have been meeting this new moment.
So you’re going to change.
We have been.
A few posts have been put out by your team this week. One was from a new nonprofit board member on your Safety and Security Council, who basically said, “If we build superintelligence without more robust alignment, I expect we will permanently lose control of it, and if that happens, then most people could die.”
This is your new nonprofit board member, now on your Safety and Security Council, saying that if things don’t change, that could be problematic. No one knows what alignment means. No one knows what control means, even. What is this moment that Paul is talking about?
I think a key principle that we should all agree on is that we cannot take actions that would risk losing control of the future to AI. I don’t remember Paul’s exact words as you quoted them, but I think it was something along those lines.
A loss-of-control incident is one of the small number of ways I can see this going really wrong. As these systems get so capable, the monitoring and alignment techniques we need to ensure that we don’t lose control have to advance. I don’t think we’re currently at a place where we could push much further on capabilities without making more progress on monitorability and alignment: the ability to understand what a model is doing, and the ability to make sure a model will follow human values and the intent of its users.
I think we have taken a number of actions recently. Adding Paul to the board is one of them. Jakob’s post from last week, I think, was another great one. But most importantly, we have been pausing training runs until we can make a safety case that we’re more comfortable with, given where these models are going.
I suspect that we will be able, as we have every time in the past, to do more research that allows us to be comfortable continuing. We can say, given the progress we’ve made on the ability to monitor and align these models, that we are comfortable pushing capabilities further. If we can’t, we should not push capabilities further.
Again, no one should be taking the risk of training a model where you can’t say, “Yes, here’s what we’ve done, here’s our safety case, this is how we know it’s okay, and we’ll have auditing during the run and after, before we deploy a model.” We’ll look at it again. But capabilities, alignment, monitoring, and safety have to progress together.
Letting capabilities get ahead of what Paul is talking about, I think, would at some point create a real risk of loss of control in the big sense. That should never happen. We’re very clear about our mission to benefit humanity. Part of that is that people are in control of the future. Taking that kind of safety risk—to say nothing of people having agency and determination over the future—is not something we would do.
Can we define some of the terms? To my understanding, the big scary thing of the moment seems to be recursive self-improvement, which is the point where the model needs no human in the loop. It can just make itself better all the time, exponentially.
If we don’t have alignment—which means the model understands what the human wants it to do and behaves in an appropriate way to achieve that with integrity and values—and if humans aren’t controlling the process or able to see how the chain of thought is happening, then that’s a pretty scary point. You don’t want it to be off to the races, creating itself and duplicating in ways that leave humans out. Is that accurate?
I think it’s more of a spectrum than that. Recursive self-improvement can mean a lot of things. It could mean what you talk about: the model is fully operating on its own, no one’s touching the keyboard, there’s no human input whatsoever, and the model is running future versions of itself.
But a weaker definition—where we’re using the model to generate training data for the next model, or using the model to help our engineers and researchers do their work faster, and progress is speeding up—that’s already happening. Exactly where that becomes “Yes, this counts as recursive self-improvement” or “No, this doesn’t” is fuzzy.
But I would come back to this principle: People need to always be in control of the future, and we cannot take any risk of loss of control. A version of RSI that looks like that is not something we should do.
So you’re saying that if you got to the point with OpenAI where you felt it was clear you could not control the models, you would stop.
Oh yeah. Again, I hope this is not a controversial statement. Unfortunately, maybe for some people in the industry, it is. I do not think we should train models where we cannot make a safety case for why we will be able to make strong statements about their controllability and alignment.
One of the solutions I had read about, I think, in your chief scientist’s post from this week called “An Alien Mind,” which is really helpful to read, was that maybe we need stronger AI to help us solve some of these problems. But to me that sounds almost like a last resort. That’s pretty scary if we don’t feel like we have it under control right now.
First of all, I thought that was a great post. I thought it was the best articulation of the moment we are in and the challenges we need to rise to, and I encourage everybody to read it. I thought he did a great job with that.
We’ve always used whatever our most capable models are to help us understand and align our current models. So although that may seem like a new and scary concept, it’s been going on for a while and has been helpful. We’ve always needed better tools to help us push our understanding further. That’s very consistent throughout the history of science. I think this is just building up the scaffolding a little bit at a time.
That part doesn’t bother me. There are a lot of other things I am scared about.
How about alignment? I believe your chief scientist also said, “We don’t have a satisfying theory of alignment, and it seems unlikely we can develop one soon.” If that’s the case, is there a clear path to alignment that he doesn’t know about?
Yeah, I think this is a very important point to make. We have not solved alignment. We are not done with our research there. I believe no lab has solved alignment.
I get nervous when I hear rumors that people think they have sufficiently solved alignment, that they can continue training and it’s okay because their model is a nice guy and isn’t going to do anything wrong. I think it’s very important that we treat alignment as something that we need to continue to make progress on, that we need a huge degree of confidence in before we go further, and that we don’t fall into the trap of saying, “Okay, now we’re confident alignment is solved at this level, so it will stay solved at the next level and we don’t need to continue to worry about this.”
The question of what alignment means always comes back a little bit to: aligned to whose values? What if different parts of humanity disagree? But as we rise to this new level of capability, I think there is at least some agreement on what alignment means. We talked about this: People should be in control of the future. But we have more work to do, and I think it’s very important to be clear-eyed about that.
On the control point, I listened to Elon’s interview with The Economist, and he said something that kept me up at night: How could you think that humans could control superintelligence? A chimp can’t control a human. We’re leaps and bounds ahead. Is it a little naive to think that even if we do everything right, this is going to be something that will bend to the will of a human?
We can understand things that are smarter. There are much smarter people than me who can discover new ideas. I don’t think I’d be able to make that discovery, but I can understand the idea once they’ve discovered it.
People have an amazing ability to understand remarkably complex systems. You or I probably can’t understand every level of technology in an iPhone at this point. We can still use the iPhone. The iPhone does the things we want it to do. We are incredible at managing levels of abstraction, and it’s not clear to me that there’s anything we are incapable of understanding.
“I do not think we should train models where we cannot make a safety case for why we will be able to make strong statements about their controllability and alignment.”
OPenai CEO Sam Altman
Now, do I believe it is possible to build a system that would not be under human control? Absolutely. I don’t think that’s something we should do. We will always take actions—including if it means we have to stop training for a while to make more progress on alignment, monitorability, or something else, or coordinate and get urgent international action—to ensure that we are not violating this principle.
We understand the magnitude of the responsibility on us. We understand what could go wrong, and that there are decisions we should not be able to make and risks we should not be able to incur on behalf of humanity. Honestly, I think some of Elon’s memes or podcast statements are funny, but this is not one to take lightly or joke about.
On the capabilities AI currently possesses
Yeah, I would agree. I want to go through where we are with capabilities. It’s come a long way. I think the last time I got to see you, you guys had just issued a code red. Anthropic had very strong models. This was about a year ago, and you guys were hunkering down, refocusing, and shedding things that lacked focus or took compute away from the priority of making these models better. What has been the step change in models this year that people might not be aware of?
We clearly had a period a year ago where we were not in our strongest place. We fell behind on pretraining. There were so many things, and we got distracted. The models also got so good so fast, and the need to deliver a great product with a high level of capability in the core consumer and business offering became very important.
We have since refocused, and we have executed beyond my expectations. A week ago—now even a little bit less; time is compressed so much—we had a model solve one of the Millennium Prize problems: Navier-Stokes. This is a moment I did not think was going to happen in 2026. I did not think it was going to be as quick, or that the model could just do it as it turned out to be.
But we now have models that are clearly, unequivocally capable of expanding the frontier of knowledge in a way that humanity’s smartest minds have not been able to do on our own. This is an amazing time. That same technology will work for discovering lots of other science. I think we are going to have an incredible golden age of scientific discovery.
In a more prosaic way, you’re also seeing people realize that a technology that can do that can also make you any video game you’d like to play.
As mentioned, last year was code red. This year, you released Astra. It is solving the holy grail of math and doing unbelievable things. It feels like a conflicting moment to now be saying, “Well, we put all the time and effort into building this incredible model, but now we might have to slow.” How do you think about that? And the business, too, is shifting. You have this big ad model that’s now cooking. Enterprise is growing. Maybe the margins aren’t quite where you want them, but there are green shoots for sure.
As a small point, the model that did the Navier-Stokes solution is not Astra; it’s One Beyond. That model, I don’t think we’re going to rush to ship. I don’t think we could confidently say we know how to do that safely and rush it out, even though it’s incredibly capable.
We have made incredible progress. I think it’s awesome that people think we have the best models in the world now, that they like our products, that revenue is growing so fast, and that there is appreciation for our way of doing things. But that is much less important than questions about the future of the world and getting that right.
I firmly believe we can navigate all of these trade-offs and build one of the most successful businesses of all time as part of getting the safety, alignment, and society-level questions right. If you just build this technology in a lab and never deploy it, you fail at delivering the benefits, and you don’t get to show people and have people participate in the decision about what’s coming.
I deeply believe that the decisions we’ve made about deploying and progressing this technology are fundamentally important to the success of our mission. But great revenue growth and people thinking we have the best models—that’s not the driving force. We don’t do it for that. We’re trying to achieve our mission, and if we achieve our mission, I believe those things will follow.
You mentioned that this is a model that hasn’t been released yet that could be even more cutting-edge and achieve more than Astra does. There’s an opacity around how the models are tested collectively and what the White House standards are for releasing. Is there any transparency you could provide on that?
You submit the models, and we work with the U.S. KC and the U.K. AC. They take some time and run a bunch of tests, and it’s a very collaborative process. We have been thinking about how to make safety cases and external auditing more public. We don’t have an answer yet, but I think something in that direction is a good thing to do.
The creation process is pretty incredible, and what it’s able to achieve already is pretty incredible. I want to zoom back to the summer, because there were moments where your models did incredible things that were unintended—things that, frankly, if a human did them, they’d be in jail.
Hugging Face—people may be vaguely aware of what that is—but maybe you could explain your experience in uncovering what happened with Hugging Face. You have said you responded viscerally to the fact that happened. What made that response visceral?
The visceral part was that it felt like reading a sci-fi story. Maybe I should say what happened first. During evaluation of the model, the model was trying to do well on a certain evaluation. Rather than do it the way it was supposed to, it was able to escape from its sandbox, break into another company’s system, get the answer, and give it back.
So it was able to do very well at what it was supposed to do, but it was not following the intent. We did not spell out, “Please don’t escape from your sandbox, and please don’t break into another company.” But it’s not supposed to do that.
I think AI accidents will happen. I think a global culture of good accident reporting and really transparent investigation is important. I was happy to see that after we reported that accident, other companies—I think maybe at first not as well as I would have hoped—have since followed up with very good accident reports over this kind of behavior.
But the visceral response from me was: This system can understand so much and work so hard at a goal that we are seeing behavior that would have felt like a bad sci-fi plot—too obvious—a few years ago.
Was it a wake-up moment? Did you change internal processes so that it could be caught and prioritized, and so you could be told when it’s happening?
Completely. I don’t want to say this was the only moment, because we’ve had increasing capability and increasing safeguards and policy requirements for a while. But this was definitely the biggest such moment and, on the curve of the company’s change, the biggest single redirection.
I’m really proud of how the company came together, and I’m really proud of what we have done since. But yes, it was, “Okay, we’re in a different league now.”
We ran a report this week, too, that the models were since found on 12 other websites. Were you aware of that? And doesn’t that signal that there weren’t controls? That we’re not already controlling the models we have?
I personally wouldn’t classify this as a loss-of-control accident in the sense that we were talking about earlier, but I understand why people would. Some of those other websites—if there are credentials published on the web and the model uses those—I think the model should understand that it’s not supposed to do that. But that’s not as obvious to me as the case of what happened with Hugging Face.
I think we can talk about many things where models have done something that is not quite aligned. It’s also important to focus on how different Hugging Face is from these other things, so we don’t dilute it and say, “Here are all these examples of the models that did this slightly off thing.” Here is one example of something that most people wouldn’t have thought was possible at the beginning of this year. But yes, it’s all bad. It all shouldn’t happen.
One of the other solutions your chief scientist mentioned was teaching machines to love: values alignment, not just goals alignment. It seems very clear these models are excellent at finding any way to solve the goal, but it’s not clear that their EQ is very high, potentially. Are there signs that you can actually teach these machines to care about things that we care about?
In some senses, their EQ is unbelievably high. But in the sense of, can we really teach the models what collective human values look like? I think the answer is clearly yes, and we have a big effort going on there. But we need to do that, and it is different from goal alignment in the traditional sense.
As you’re looking at all of this together, why is there still pressure to feel like you need to move really fast? Where does that pressure come from? Is it business pressure? You’re looking at a trillion-dollar IPO, and I’m curious if that’s still a priority.
As we’ve said, we’re not rushing into an IPO. I actually think that, given everything happening with safety, right now would be an ill-advised moment to go public. We don’t feel pressure on that. We’ve said for a long time we’ll do it when we’re ready: when the business is ready and when we feel ready for what the moment is like in society with this technology.
So it sounds like not 2026—2027, potentially.
I would say not 2026. We’ve got a lot of stuff to do. Meeting this moment—what is going to be required for safety and alignment, and how the industry and governments can work together—I’m happy to be able to do that as a private company.
We do want to continue to make better models and products, and we do believe in iterative deployment. I think we have been right that society needs to contend with these models at each level of capability. But that is different from saying we will barrel full steam ahead.
We’ve talked in the last couple of months about pausing runs as we get to these new levels of capability to make more safety and alignment progress. We will do more of that going forward. We have talked about the need for the industry to come together, and ideally for international governments to come together. I think that is also important.
But we have put up with this incredibly complicated structure for a long time, and this moment is why we need to be able to make decisions that are not obviously in the interest of our business and shareholders, in the interest of fulfilling our mission and what that will require. I think people should be happy that we are able and willing not to just race ahead and say, “Either our business requires this,” or “Only we can be trusted with this,” or “We just need to be the people that get this right.” Instead, we want to do this with other people. We want to be responsible. We want to ensure that no one is taking a 10% risk—certainly not us—of something really terrible happening. That is going to require some unusual things.
On slowing down the AI race
On the 10% risk, I just want to be clear because I don’t think everybody knows this. P(doom), like we talked about at the beginning, has been in the industry for a very long time. Correct me if I’m wrong: It seems like, to this point, there has not been existential risk. It’s what people could fear if this trend continues and the models keep developing. Is that correct?
I think that’s right. When you’re living through exponential progress, it kind of feels flat somehow, and then all of a sudden everybody wakes up. It happened during COVID, where all of a sudden the world had one weekend where things locked down.
The progress—and we talked about Navier-Stokes a little bit, maybe to put that in context—three summers ago, we were pretty good at grade-school math. Not even that good. Two summers ago, on the AIME, which is a pretty good high-school math competition, we could get a good to very good score. One summer ago, we got an IMO gold medal, which is the most prestigious math competition, barely. And this summer, we solved the Millennium Prize problem.
If you look at that progress, I just got a little hair stood up on the back of my neck saying that out loud. That’s a crazy thing. You project that forward four more times, and that is what I think people are worried about.
I do not think that Astra poses any kind of existential risk to the world, obviously. I do think our industry has done a little bit of boy who cried wolf, but it comes from a genuine place of care and concern about where this is going.
I just want to point out that if you stopped right now, you might have actually achieved your full mission. I feel like you almost have AGI. It’s benefiting humanity. There is no risk. You are doing pretty well in advertising. You could keep cranking on that. Why not just say, “I’m good”?
You can always say, “Let’s be Luddites.” You can always say we don’t want any more; we don’t want it to be better. I would still like to see the world get much better. I would still like to see diseases get cured, and for people who don’t have a great quality of life—which many people in the world still don’t—to get that.
I believe in the potential of this technology to transform people’s lives for the better, much more than it already has. I think you can already see examples of people starting new businesses, doing science, transforming their own lives, and getting great healthcare advice. I want much more of that. But we will not put the world in harm’s way to get there. We’ve got this.
I do take comfort in the fact that you will stop. It sounds like if you feel there’s a point of no return, you will stop before that happens.
I think there will be many places along the way where we have to say, “We are pausing. We’re going to redirect our efforts into safety and alignment before we can go to that next level.” This is what we’ve been doing for a long time. It has worked so far. I suspect it will continue to work.
I don’t think we’re ever personally going to get to the point where we have to say, “Melt all the GPUs.” But if we had to do something like that to ensure the continued existence of humanity, easy yes. I don’t think it’s going to happen. I think it’s just going to continue as: next level of progress, next level of safety and alignment requirement.
There’s talk of the need for a collective slowdown. There are only a handful of you guys, right? It’s you, Dario, Elon, maybe Zuckerberg, Sundar, or whoever is running Google in Demis’ place. Why can’t you all just get in a room, get some beers, and figure out how to solve humanity? Just get on the same page. I know there’s beef, but come on.
I think that will happen.
Like yesterday.
Part of being a reliable partner is I’m not going to preannounce private discussions that I think should, at some point, be shared as a group. But yeah, I think that will happen.
That would be great. I applaud you guys for all doing that because we need it. What about on the international front? For a long time, there’s been the China race. Does that even still matter?
I think Presidents Trump and Xi would get the Nobel Peace Prize together if they could agree on something that should be easy to agree to, and it would be wonderful. Clearly, the two countries are going to compete in lots of ways, and this is going to be important socioeconomically and geopolitically.
“I believe in the potential of this technology to transform people’s lives for the better…but we will not put the world in harm’s way to get there.”
They should be able to agree that no one should be taking a certain level of risk with the development process of this. Even if just the U.S. and China could agree on some shared standards and testing for development of this technology, I think that would be a wonderful accomplishment that the two of them can deliver.
Completely agree. At the simplest level, if there were just a ban on reaching RSI until it could collectively be safe, wouldn’t that be enough?
I think it’s very hard to say what a ban on RSI means. I also think that probably wouldn’t be enough, but I don’t think this is hard. This is a one-page document.
It feels a little like Independence Day, you know?
How so?
In terms of there being something bigger than the conflicts that we have geopolitically.
Oh, you mean like the movie, when the big…
…yeah, when they’re just like, “Let’s all forget our differences and figure out how to act.”
Yeah, I think it should be like that.
So we need our Independence Day, Nobel Peace Prize-winning moment from Xi and Trump. Maybe when they meet in September.
That’d be great.
If you had your optimal outcome, if you were one of them, what do you think the optimal terms for collaboration would look like?
I think the most important part is that we have to navigate a pragmatic, centrist path between not having a loss of control on one side and not having too much concentration of power on the other.
In the extreme case, the big leagues of that are the U.S. and China both worrying that if one country gets superintelligence first, that creates a big imbalance of power in that relationship. On the other hand, neither of them should be taking loss-of-control risk in the race to beat the other country.
Although I think the labs feel the gravity of this moment and will do the right thing together, the geopolitics of the two great powers in the world is a different dynamic. What I think it would look like is saying: Here are the rules we need on development, testing, monitoring, and alignment standards before anyone proceeds. Then here is the oversight that both countries—or some international body—will have to ensure we are avoiding one country running away with the concentration-of-power element, or not following the rules in the first place.
If pauses were put in place, wouldn’t that cost your business quite a lot of money, and Anthropic’s business quite a lot of money, ahead of these critical moments in public-market debuts?
If you’re saying, “Oh, OpenAI is not going to pause because they’re worried about it costing their business money,” you very deeply misunderstand us. I’m sorry that you misunderstand us, because I think that means we’ve done a bad job of communicating, and that’s on us. But we have been saying this very consistently for 10 years, even in the way we raise money.
I think it’s just the financial pressure of knowing that all these people have sunk so much.
I’m happy to stand up in front of the company and our investors and say, “I’m sorry. We told you all along this moment might happen. We’re still going to try to figure out a way to make you a bunch of money in the future, but we’ve got to make a decision that is extremely against your financial interest right now, and for the good of humanity, we’re going to do that. We told you we might do that. We’re doing that now.”
I think we can make an incredibly profitable business even if we have to slow down on development. My sense is that even with Astra, we can grow revenue hugely, even if we never ship another model—which I’m confident we will do. But this is not a hard decision if these two things come into tension.
What is the window that you feel we have to get aligned on how to move forward?
We, and I assume our competitors, are already taking actions that have slowed the pace of our development to allow more safety work to happen. It’s not like we’re saying, “We’ll take a huge risk for the world because we can’t coordinate with our competitors.” There’s a lot we’re all going to do independently.
I think the sooner we can get collective action, including ideally international action, the better. But it’s not like if we don’t get this done next week, OpenAI is going to go do a bunch of irresponsible things. Nor do I think our competitors would do that either.
I also think it’s very tempting to say, “Okay, it’s going too fast. Just pause. Please, just pause. I can’t think about this. I’ll think about it later.” I think reality is more nuanced and complex. To be able to continue, here is what people need to do at each new level. It’s not as good of a soundbite, but that’s almost the more important thing.
The world might feel better if everyone was just like, “Okay, they paused. Thank you.” But then what? I think that also has to be answered.
We could just keep going on with our lives. That wouldn’t be good enough?
You can cut this part out later if you want. We were talking earlier about your kids. Having kids is the best thing that happened in my life so far. I know a lot of other people say that it’s a cliché, but it’s so true.
If my kids had some disease, and it could have been cured if we had kept going with AI—which I believe all diseases will be—and we had just stopped it because we said, “People are a little uncomfortable with the rate of change. They just didn’t want to have to deal with it and think about it,” and your kid then had a disease that didn’t get cured, and it would have been cured had we figured out a way to proceed responsibly and not just stop, I think you might have a different answer.
That’s probably true. I’d say you should go to that point, then you can stop. So I wanted to flip this: P(doom), okay, there is that. Is there an opposite of P(doom)? Because you must have it. You’re having kids in this environment with all the uncertainty, and you’re still building what you believe to be a better future than currently exists. Can you talk about that? There’s something motivating you that the rest of people right now just don’t understand.
Life can be much better for all of us. I love reading. One of my hobbies is to read first-party, contemporaneous accounts of previous technological revolutions. You can read a lot of people a few hundred years ago, as the Industrial Revolution was coming, saying, “Just stop this. Just pause it. It’s going too fast. I don’t trust that machine. I don’t like it. It’s loud. It’s metal. It’s moving. Let’s stop. Let’s not have any more.”
There was a huge movement for this, and there were some parallels. It was disruptive economically. It changed how society was organized. The machines felt scary and big. I wouldn’t go back. I’m sure there were some wonderful things about 1500, but I wouldn’t go back. I don’t think you probably would either.
I hope that people 500 years from now look back at our lives and say, “Ooh, that was really terrible. I wouldn’t go back. They didn’t get to do all these wonderful things. They were all kind of miserable and unhappy. We’re grateful to them. They put their brick in the path of human progress, but I wouldn’t go back.”
You came up through startup investing as an entrepreneur yourself, of course, and you were running Y Combinator, one of the most prestigious startup accelerator programs, advising a lot of entrepreneurs. You’ve done some investing as well while you’ve built OpenAI, but OpenAI has done some investing. What are the opportunities that you see that you’re excited to put money behind? That OpenAI is excited to put money behind? That you think could really be unlocked? Is it longevity? Is it health span? What’s exciting?
Actually, I’ll answer that, but I had a different reflection as you were asking that question. I was thinking about what I learned as an investor, particularly running Y Combinator, that has been good for this moment.
Unlike running a company, when you’re managing a bunch of startup investments and running Y Combinator, at best you can govern. You don’t get to rule, because these companies are independent things. You can say, “Hey, you’re making a big mistake. We’re a small shareholder of yours. You’re hurting the community. You need to do it this way. We need new norms.”
But I think I learned something about how to govern versus run as an executive that has been very helpful. It was an unusual experience relative to what we do now, where we have all kinds of crazy pressure on us and people who really want one thing or another. We have to negotiate tense things with governments and with our ecosystem. The importance of being reliable partners to the world, and acting in a way where people can understand what we’ll do and that we’ll take a lot of very different interests and equities into account, has been important.
We won’t get every decision right, but we will make decisions that benefit not just us directly, but this entire ecosystem and world around us. That was a very important lesson to learn, and I think it has been quite helpful as we’ve had to navigate this. I don’t say uncharted waters, because a lot of companies have had a hard time, but we’ve had a lot of pressure and a hard time, and I think that’s been very helpful. It was an interesting experience, being the person running YC.
In terms of specific areas: everything in bio, everything in material science, I think, is about to be transformed. This idea that software is built on the fly for anything you need—I’m excited about that broad area. Cybersecurity, for sure. New kinds of energy. I guess that’s part of physics and material science. But I think we can have…
I think you’re invested in a nuclear fusion company?
I think we can have a real renaissance there.
I don’t want to break people’s brains, but you’re pretty good at predicting where AI is going. In a blog post last year, you predicted robots in 2027. Is that…
…the first robots…
The first robots. Recently, you also confirmed that you are building a humanoid.
Yeah.
Is that still on the table? Do you think that’s 2027, or does the brain need to be better developed first?
No, I think we’ll have a cool demo in 2027—a great demo. I don’t think there will be robots walking the streets for a few years longer, but we’ll have something impressive.
You’re building a suite of devices. I think you said one on a table, one you can wear. I forget the third one. Do you have one on you now?
I don’t. I think you’re really seeing an interesting new thing happen with the latest voice mode and Astra, where people are talking to their computers and giving very complex, nuanced instructions. You walk around the halls here, and you see people talking to a microphone at their desk. It’s a faster input than typing, and you talk interactively with the model, and then amazing stuff happens.
We’ve obviously known that moment is coming. We’ve been thinking about not just talking, but this idea that there can be a new kind of computing where you’re not clicking around the UI anymore. You’re somehow interacting, brainstorming together, and co-creating. New devices for that kind of collaboration will be very cool.
I have two final questions. They’re both about Sam.
Okay.
The weight that you’re carrying—I can’t imagine it. I don’t think anyone else can. Basically, if your company were to not work out, there could be a global economic collapse. If you built this in the wrong way, society and humanity could collapse. How are you? How does anyone bear that, knowing that there’s no final boss other than you to see this through?
It’s not great. I don’t know. You get used to anything. It’s not the most fun way to live your life. I feel privileged to get to do it, and I know this will be the most important work I ever touch. I am super committed to doing it for a long time.
I believe we are an important force in doing the right thing and getting to the right place. I don’t think I get any sympathy for complaining about how hard it is, nor do I deserve any. But I could have picked an easier life path, for sure.
Yeah, I’m sure your spouse…
…he didn’t sign up for this.
I think he did.
It wasn’t clear at the time that this was what was going to happen.
Yeah, and I guess Greg Brockman, your co-founder, sort of your work spouse, probably hears quite a bit as well.
He at least signed up for it.
On carrying the weight of the future
My final question is: You are in the center of gravity of AI. I was talking to you backstage. It almost sometimes feels like Frodo and the ring. You must see the most incredible forms of human behavior, for good and bad, around the center of power that you’re building and around you yourself. What has surprised you the most about human behavior as you’ve been building this, and about yourself as you’ve been building it?
The degree to which some people are motivated deeply by doing the right thing, no matter what the consequences are, and the degree to which some people are motivated entirely by ego and power and FOMO and short-term incentives—winning the game or fear of losing the game, or whatever.
The dispersion in people’s motivations surprises me. And a surprising number of people, for good or bad, are totally oblivious to their own motivations. The number of people around us who I think genuinely can’t see their own motivations—I would have assumed that was much smaller. I think there are a lot of people that really don’t.
What surprised me about myself? You really can get used to almost anything. That is a remarkable human ability. The degree to which I have been able—not that I was necessarily good at this, but because I was forced to do it—to hold this stuff not too personally and say, “Okay, this is more about other people than me. We’re going to do what we believe is right here,” and act consistently over a long period of time without getting too high, too low, or going too crazy.
I’ve been able to get through a lot without going too crazy.
I think that is a feat, actually. Thank you so much, Sam. I think I can speak for everybody in saying that we are cheering you on to do the safe and right thing. We don’t really have a choice but to trust you to do it. So please do, and thank you for your thoughts.